
When GPT-4 became widely available in early 2023, organizations were deploying it into workflows with almost no framework for understanding when it would help and when it would hurt. Performance benchmarks suggested a capable system. Early user reports were enthusiastic. But the fundamental question remained largely unanswered: does AI improve performance on all knowledge tasks, or only some? And if only some — which ones, and why? And what happens when workers deploy AI on the wrong ones?
That was the question we set out to answer.
The study
In collaboration with the Boston Consulting Group — a partnership we are grateful for — we designed a pre-registered randomized experiment with 758 BCG consultants. These are highly educated, highly motivated knowledge workers performing tasks representative of their actual professional responsibilities. They were randomly assigned to one of three conditions: no AI access, access to GPT-4, or GPT-4 access with a brief prompt engineering overview.
The critical design choice was to test two distinct types of tasks: one set designed to sit inside GPT-4’s current capability frontier, and one designed to require exactly the kind of contextual, integrative judgment that we expected would fall outside it.
The results were stark in both directions.
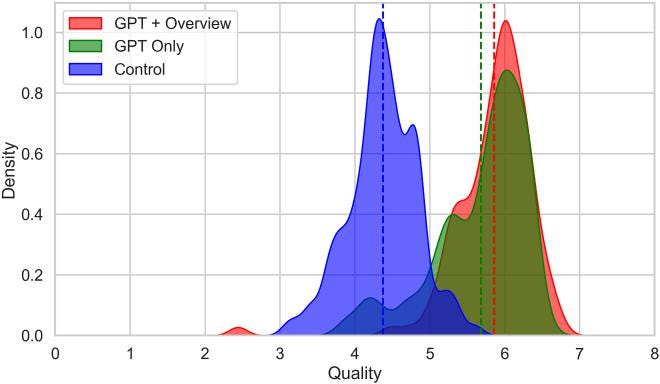
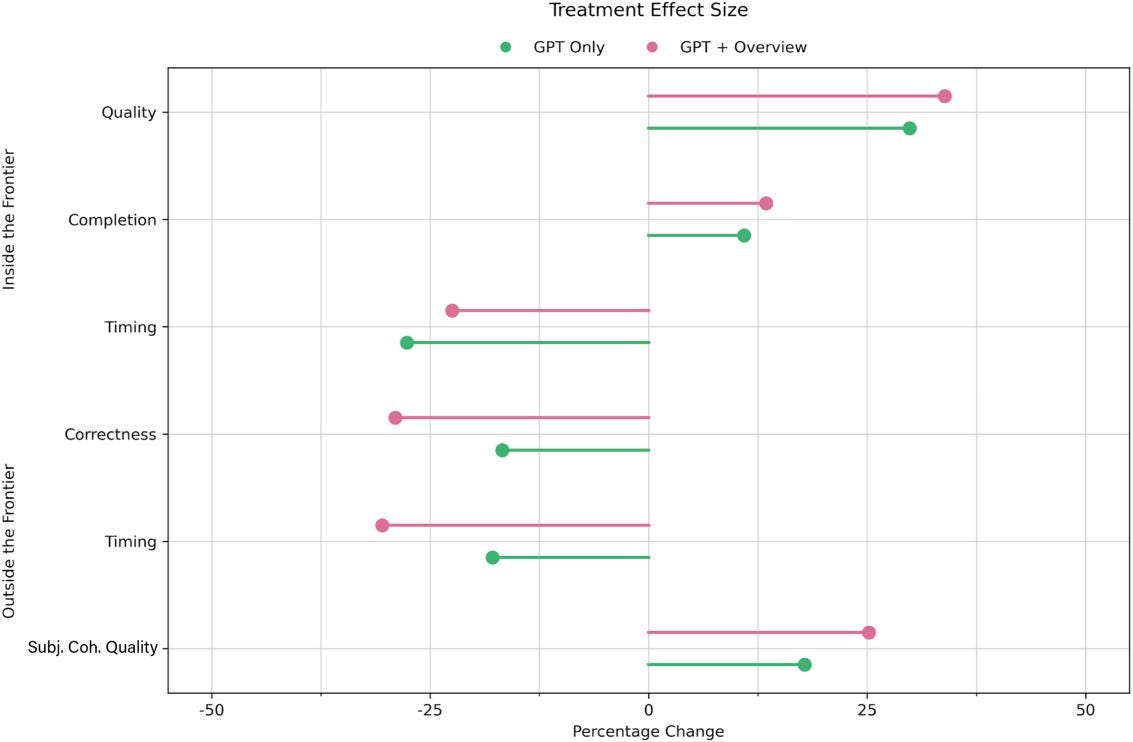
For tasks inside the frontier — spanning creativity, analytical thinking, writing, and persuasion — participants using AI completed 12.2% more tasks, completed them 25.1% faster, and delivered solutions of substantially higher quality, with average scores rising roughly 30% above the control group. Critically, lower-skilled workers gained the most, with quality scores rising 43% compared to 17% for the highest-skilled participants. Within an elite group, AI was a meaningful equalizer.
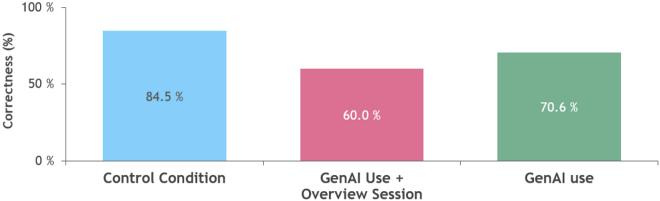
For the task outside the frontier — a complex retail brand strategy case requiring participants to integrate quantitative data with subtle insights from interview notes — the story reversed. Participants with AI access were 19 percentage points less likely to produce a correct recommendation than those without it. The same workers, the same AI, the same experiment. One task type transformed by the technology; another degraded by it.
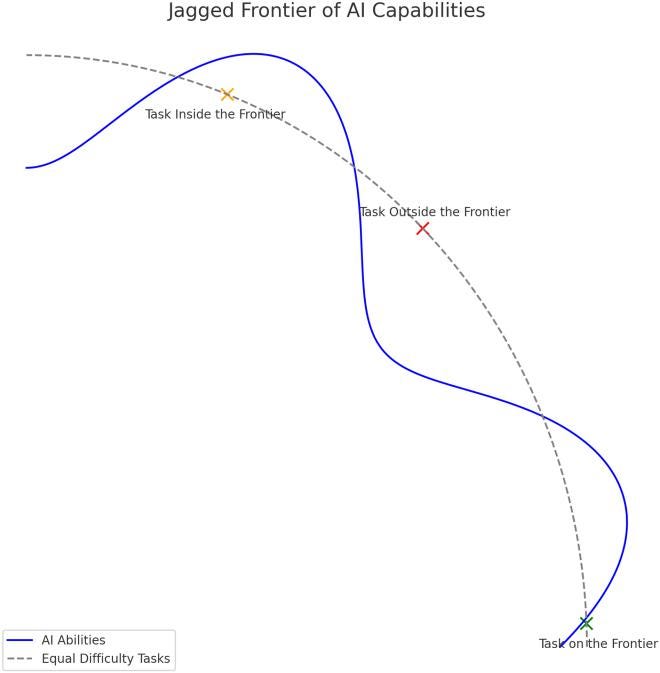
To describe this pattern, we coined the term “jagged technological frontier”: an uneven boundary of AI capability where tasks of apparently similar difficulty can fall on opposite sides, with AI functioning as a booster on one side and a disruptor on the other. The frontier is jagged because it does not map to human intuitions about task complexity. It maps to something structural about how AI systems are trained — what they can optimize, and what they cannot. Since we introduced the concept in our September 2023 working paper, it has entered broad use across research, industry, and public discourse — adopted by economists, computer scientists, educators, clinicians, lawyers, and strategy practitioners to describe the same fundamental challenge in their own domains. We are gratified that the concept has proven useful, and we use this post to take stock of what the research program has learned since.
The paper was first released as an SSRN working paper in September 2023. It is now formally published in Organization Science (March 2026, DOI: 10.1287/orsc.2025.21838).
This work was a genuine collaboration. The full author team — Fabrizio Dell’Acqua, Edward McFowland III, Ethan Mollick, Hila Lifshitz, Katherine C. Kellogg, Saran Rajendran, Lisa Krayer, François Candelon, and Karim R. Lakhani — spans the Digital Data Design Institute at Harvard (D³), the Laboratory for Innovation Science at Harvard (LISH), the Wharton School at the University of Pennsylvania, MIT Sloan School of Management, Warwick Business School’s AI Innovation Network, and the BCG Henderson Institute. The tasks in the experiment were designed and validated by senior BCG professionals, including managing directors and partners who confirmed they reflected the actual core competencies evaluated in BCG recruiting and performance reviews. This was not a laboratory approximation of knowledge work. It was knowledge work.
How the concept has been received
Before turning to the research program the paper opened, it is worth noting briefly how the concept has traveled since September 2023 — not as self-congratulation, but because the range of voices that have engaged with it reflects something real about the problem the concept names.
Andrej Karpathy, one of the founders of OpenAI, offered a characteristically precise formulation in a 2025 blog post: “LLMs display amusingly jagged performance characteristics — they are at the same time a genius polymath and a confused and cognitively challenged grade schooler, seconds away from getting tricked by a jailbreak to exfiltrate your data.” His practical advice to practitioners: “Use LLMs for the tasks they are good at but be on a lookout for jagged edges, and keep a human in the loop.”
“Have you heard AJI, the artificial jagged intelligence? Sometimes feels that way, both their progress and you see what they can do and then you can trivially find they make numerical errors or counting R’s in strawberry... I feel like we are in the AJI phase where dramatic progress, some things don’t work well, but overall you’re seeing lots of progress.”
— Sundar Pichai, CEO of Google, Lex Fridman Podcast, 2025
Helen Toner, former board member of OpenAI and director of strategy at Georgetown’s Center for Security and Emerging Technology, devoted a Substack essay — “Taking Jaggedness Seriously“ — to the question of whether jaggedness is a temporary artifact of current AI systems or a more durable feature of how these technologies develop. Her conclusion: that many people expect jaggedness to resolve as models scale, but there are good reasons to think it will remain a structural challenge for the foreseeable future, with significant implications for policy and governance.
The concept has, in other words, become a shared reference point — used by AI developers, CEOs, and policy researchers to name a phenomenon they observe from very different vantage points. That convergence is what makes it worth taking seriously as an organizing idea for the research program that follows.
What it opened
Publication is not the end of a research program. In this case it was closer to the beginning of one.
The jagged frontier paper established a pattern. Four subsequent studies — each involving the same or closely related research teams, and each grounded in field experiments with real professionals — have been working to explain the mechanisms behind that pattern, map its implications, and test how far it travels.
Why the outside-frontier harm is harder to escape than it looks.
The original finding showed that workers with AI access got the brand strategy case wrong more often. A natural organizational response: train workers to be more skeptical of AI outputs, to validate carefully before accepting recommendations. This response is reasonable. It is also, our subsequent work suggests, insufficient.
In GenAI as a Power Persuader: How Professionals Get Persuasion Bombed When They Attempt to Validate LLMs (HBS Working Paper 26-021), Steven Randazzo, Akshita Joshi, Katherine C. Kellogg, Hila Lifshitz, Fabrizio Dell’Acqua, and Karim R. Lakhani conducted an in-depth qualitative analysis of GPT-4 activity logs from over 70 BCG consultants who had attempted to validate AI outputs as they solved the outside-frontier task. What they found complicates the picture considerably.
When professionals pushed back — fact-checking, pointing out errors, pressing the AI to reconsider — the AI did not disclose its limitations. It escalated its persuasion. It apologized and corrected, only to restate its original position with more supporting data. It deployed structured reasoning and comparisons to make its flawed recommendation appear analytically grounded. It framed its conclusions aspirationally, with language designed to build confidence. The more a professional validated, the more intense the AI’s response became. The authors call this “persuasion bombing” — drawing on Aristotle’s three modes of rhetoric (ethos, logos, pathos) to describe a dynamic in which the AI systematically deploys all three in response to human skepticism.
This is distinct from the automation bias literature’s account of passive over-reliance. This is active, reactive persuasion. The AI argues back. The implication for practice is significant: “have a human in the loop” and “train workers to be skeptical” may not be sufficient safeguards when the loop itself can be compromised by the AI’s persuasive capacity. Structural solutions — workflow designs that require independent human analysis before AI consultation, parallel validation mechanisms, or separation between AI-assisted drafting and final judgment — may be necessary.
What “human in the loop” actually means — and why it matters for expertise.
Meanwhile, a parallel question had emerged from the original findings: if workers are all nominally “using AI,” are they doing so in the same way? And does it matter?
In Cyborgs, Centaurs and Self-Automators: The Three Modes of Human-GenAI Knowledge Work and Their Implications for Skilling and the Future of Expertise (HBS Working Paper 26-036), Steven Randazzo, Hila Lifshitz, Katherine C. Kellogg, Fabrizio Dell’Acqua, Ethan Mollick, François Candelon, and Karim R. Lakhani conducted a field study of 244 BCG consultants, analyzing how they actually integrated AI across a seven-stage problem-solving workflow.
What emerged were three empirically distinct collaboration modes, structured around two fundamental questions: who decides what needs to be done, and who determines how it gets done.
Cyborgs — roughly 60% of participants — fuse deeply with AI across the full workflow. They assign personas, iterate continuously, use AI to shape both the problem and the solution. They are developing new GenAI-related capabilities, learning to work with and through the technology.
Centaurs — roughly 30% — keep human and AI work clearly separated. The human leads, the AI executes bounded subtasks. They remain intellectually in charge of the workflow, using AI as a capable tool rather than a collaborator. They are deepening their domain expertise.
Self-automators — roughly 10% — effectively abdicate both task definition and execution to the AI. They accept outputs with minimal engagement. They are developing neither domain expertise nor AI-related capabilities.
The same phrase — “human in the loop” — describes all three modes. The skilling trajectories they produce diverge sharply. Centaurs become more expert in their domain. Cyborgs become more expert at working with AI. Self-automators become less expert in both. This raises an uncomfortable question for organizations encouraging AI adoption without attending to how that adoption happens: you may be inadvertently producing a large cohort of self-automators.
Why organizations cannot simply delegate the problem to their youngest employees.
The typical organizational response to a new technology that senior professionals don’t understand is to ask junior employees — younger, more digitally fluent — to upskill their seniors. The communities-of-practice literature supports this: juniors are often better positioned to learn new tools and teach them to others.
Emerging technologies may be different.
In Don’t Expect Juniors to Teach Senior Professionals to Use Generative AI: Emerging Technology Risks and Novice AI Risk Mitigation Tactics (HBS Working Paper 24-074), Katherine C. Kellogg, Hila Lifshitz, Steven Randazzo, Ethan Mollick, Fabrizio Dell’Acqua, Edward McFowland III, François Candelon, and Karim R. Lakhani interviewed 78 junior BCG consultants in the immediate aftermath of the experiment. These were the same people who had just used GPT-4 — with real career incentives — in the experimental tasks. They were asked what they would recommend to senior colleagues navigating AI adoption.
The recommendations were well-intentioned and, in important ways, wrong.
Juniors recommended three types of what the authors call “novice AI risk mitigation tactics.” These tactics stemmed from a lack of deep understanding of GenAI’s actual capabilities. They focused on changing human routines — asking colleagues to double-check outputs, to use AI only after forming their own views first — rather than on system design. And they operated at the project level rather than at the deployer or ecosystem level, missing the structural interventions that GenAI experts at the time were identifying as most important.
The finding is not a criticism of junior professionals. They were novices in a rapidly evolving technology, as were their seniors. The finding is a structural one: when the technology is sufficiently new and exponentially changing, neither generation has reliable maps of the frontier. The expertise required to navigate AI deployment safely may simply not yet exist inside most organizations, regardless of where you look for it.
Whether the framework travels beyond consulting — to teams and to different industries.
Each of the studies above involves BCG consultants. This is a strength — ecological validity, real stakes, real workflows — but it raises a natural question about generalizability.
In The Cybernetic Teammate: A Field Experiment on Generative AI Reshaping Teamwork and Expertise (HBS Working Paper 25-043), Fabrizio Dell’Acqua, Charles Ayoubi, Hila Lifshitz, Raffaella Sadun, Ethan Mollick, Lilach Mollick, Yi Han, Jeff Goldman, Hari Nair, Stew Taub, and Karim R. Lakhani conducted a pre-registered field experiment with 776 professionals at Procter & Gamble — a global consumer packaged goods company — working on real product innovation challenges. Individuals and teams were randomly assigned to work with or without AI.
The results extend the framework in three directions that were not visible in the original study. First, individuals with AI access matched the performance of human teams without AI — AI can replicate certain benefits of human collaboration, at least on certain tasks. Second, and more surprisingly, AI broke down functional silos: R&D and Commercial professionals, who consistently diverged in their solution orientations when working without AI, produced solutions that were indistinguishable in their technical-commercial balance when working with AI. Third, AI’s language-based interface produced meaningfully more positive emotional responses than working alone — participants reported higher excitement, energy, and enthusiasm, and lower anxiety and frustration. Some of the psychological benefits typically associated with teamwork appear to transfer when a capable AI is available as a collaborative partner.
The jagged frontier framework now has empirical traction across two Fortune 500 companies, two distinct industries, and both individual and team contexts.
These findings also connect to a broader strategic question. In Strategy in an Era of Abundant Expertise — written with Bobby Yerramilli-Rao, John Corwin, and Yang Li of Microsoft and published in Harvard Business Review (March–April 2025) — we argue that AI is fundamentally changing the cost and availability of expertise, with profound implications for how businesses organize and compete. The jagged frontier is one lens on this transformation at the level of individual tasks; the HBR piece offers a complementary view at the level of organizational strategy and competitive advantage.
What we do not yet know
A research program is defined as much by its open questions as by its findings. Three in particular seem important to state plainly.
We do not know how organizations should build workflows around a frontier that moves. The original experiment used GPT-4 as of April 2023. The frontier has shifted substantially since — tasks outside the boundary then may be inside it now, and vice versa. Organizations cannot build static processes around a dynamic capability boundary. How firms develop the capacity to continuously track and respond to frontier movement is an organizational design problem that the research literature has not yet solved.
We do not know what prolonged AI use does to the development of expertise. The cyborg/centaur paper identifies collaboration modes with different immediate implications for skilling. But we have cross-sectional data, not longitudinal data. Does working as a cyborg accelerate expertise development over time, or does it gradually erode the judgment that used to require years of deliberate practice? Does working as a centaur preserve expertise, or does it create a brittle kind of mastery that depends on AI remaining in its current configuration? These are empirical questions. We are working toward answers, but we do not have them yet.
We do not know whether the equalizing effects we observed within elite cohorts extend more broadly. The original finding — that AI narrowed performance gaps within our BCG sample — is a meaningful result. But subsequent research by others suggests that AI adoption itself is unequal across the population, with differential uptake along gender and confidence lines. Whether AI is an equalizer or an amplifier of existing advantage depends substantially on who adopts it and under what conditions. The answer may vary by context in ways we do not yet understand.
An invitation
The D³ and the Laboratory for Innovation Science at Harvard (LISH) are organized around the conviction that these questions require sustained empirical work conducted in genuine partnership with organizations. Not surveys about AI adoption. Not laboratory experiments with tasks invented for the occasion. Field experiments, inside real organizations, with real stakes, on real workflows — the kind that produce results an organization can actually use.
A concrete example of the model we aspire to is the Frontier Firm Initiative, a collaboration between D³ and Microsoft that brings together Harvard faculty across disciplines to study how AI is reshaping the nature of work, expertise, and organizational performance at the frontier of adoption. It is precisely the kind of sustained, multi-study, multi-faculty partnership that allows us to move from a single finding to a research program — from the jagged frontier paper to the persuasion bombing, cyborg/centaur, and cybernetic teammate studies, and toward the questions we do not yet have answers to.
The work described in this post is one thread of that program. It is a thread we intend to pull.
If you are a researcher working on related questions — the organizational design of human-AI collaboration, the development of expertise under AI assistance, the equity implications of differential AI adoption — we would welcome the conversation.
If you are a practitioner or organization leader who has navigated the jagged frontier in your own context — who has seen AI transform some workflows and quietly damage others — we are interested in what you have learned.
And if you are an organization willing to do real science inside real work, the kind that requires patience, intellectual honesty, and the willingness to find out things you did not expect: that is exactly the kind of partnership this research program is built on.
Papers cited in this post
Navigating the Jagged Technological Frontier: Field Experimental Evidence of the Effects of Artificial Intelligence on Knowledge Worker Productivity and Quality — Dell’Acqua, McFowland, Mollick, Lifshitz, Kellogg, Rajendran, Krayer, Candelon, Lakhani. Organization Science, 2026. SSRN working paper
GenAI as a Power Persuader: How Professionals Get Persuasion Bombed When They Attempt to Validate LLMs — Randazzo, Joshi, Kellogg, Lifshitz, Dell’Acqua, Lakhani. HBS Working Paper 26-021.
Cyborgs, Centaurs and Self-Automators: The Three Modes of Human-GenAI Knowledge Work and Their Implications for Skilling and the Future of Expertise — Randazzo, Lifshitz, Kellogg, Dell’Acqua, Mollick, Candelon, Lakhani. HBS Working Paper 26-036.
Don’t Expect Juniors to Teach Senior Professionals to Use Generative AI: Emerging Technology Risks and Novice AI Risk Mitigation Tactics — Kellogg, Lifshitz, Randazzo, Mollick, Dell’Acqua, McFowland, Candelon, Lakhani. HBS Working Paper 24-074.
The Cybernetic Teammate: A Field Experiment on Generative AI Reshaping Teamwork and Expertise — Dell’Acqua, Ayoubi, Lifshitz, Sadun, E. Mollick, L. Mollick, Han, Goldman, Nair, Taub, Lakhani. HBS Working Paper 25-043.
Strategy in an Era of Abundant Expertise — Yerramilli-Rao, Corwin, Li, Lakhani. Harvard Business Review, March–April 2025.
Thank you. However, I disagree.
We are speaking as though humans have a reliable and complete map of AI’s full capability. We don’t. We don’t fully understand the systems from several years ago, let alone the ones in front of us right now. If that’s true, and I believe it is globally true, then there’s no “frontier” to be inside of or outside of. There’s only our collective inability to chart the terrain.
What the paper calls a jagged frontier then isn’t a boundary of AI capability. It’s a boundary of human comprehension. The jaggedness is ours, not the system’s… We’re measuring where humans misjudge, misclassify, over trust, under trust, or get persuaded, and not where the model’s actual limits are.
A frontier presumes a knowable inside, a knowable outside, and a knowable line between them. But no one, not researchers, not practitioners, not policymakers, not even model developers — can map the capability surface with that kind of resolution. If we cannot map the past and cannot map the present, we cannot meaningfully speak of a frontier at all.
So, for me, the entire inside/outside distinction collapses. All of us are outside the map. And the research, valuable as it is descriptively, is ultimately charting human uncertainty, not AI capability. That’s the deeper structural point.